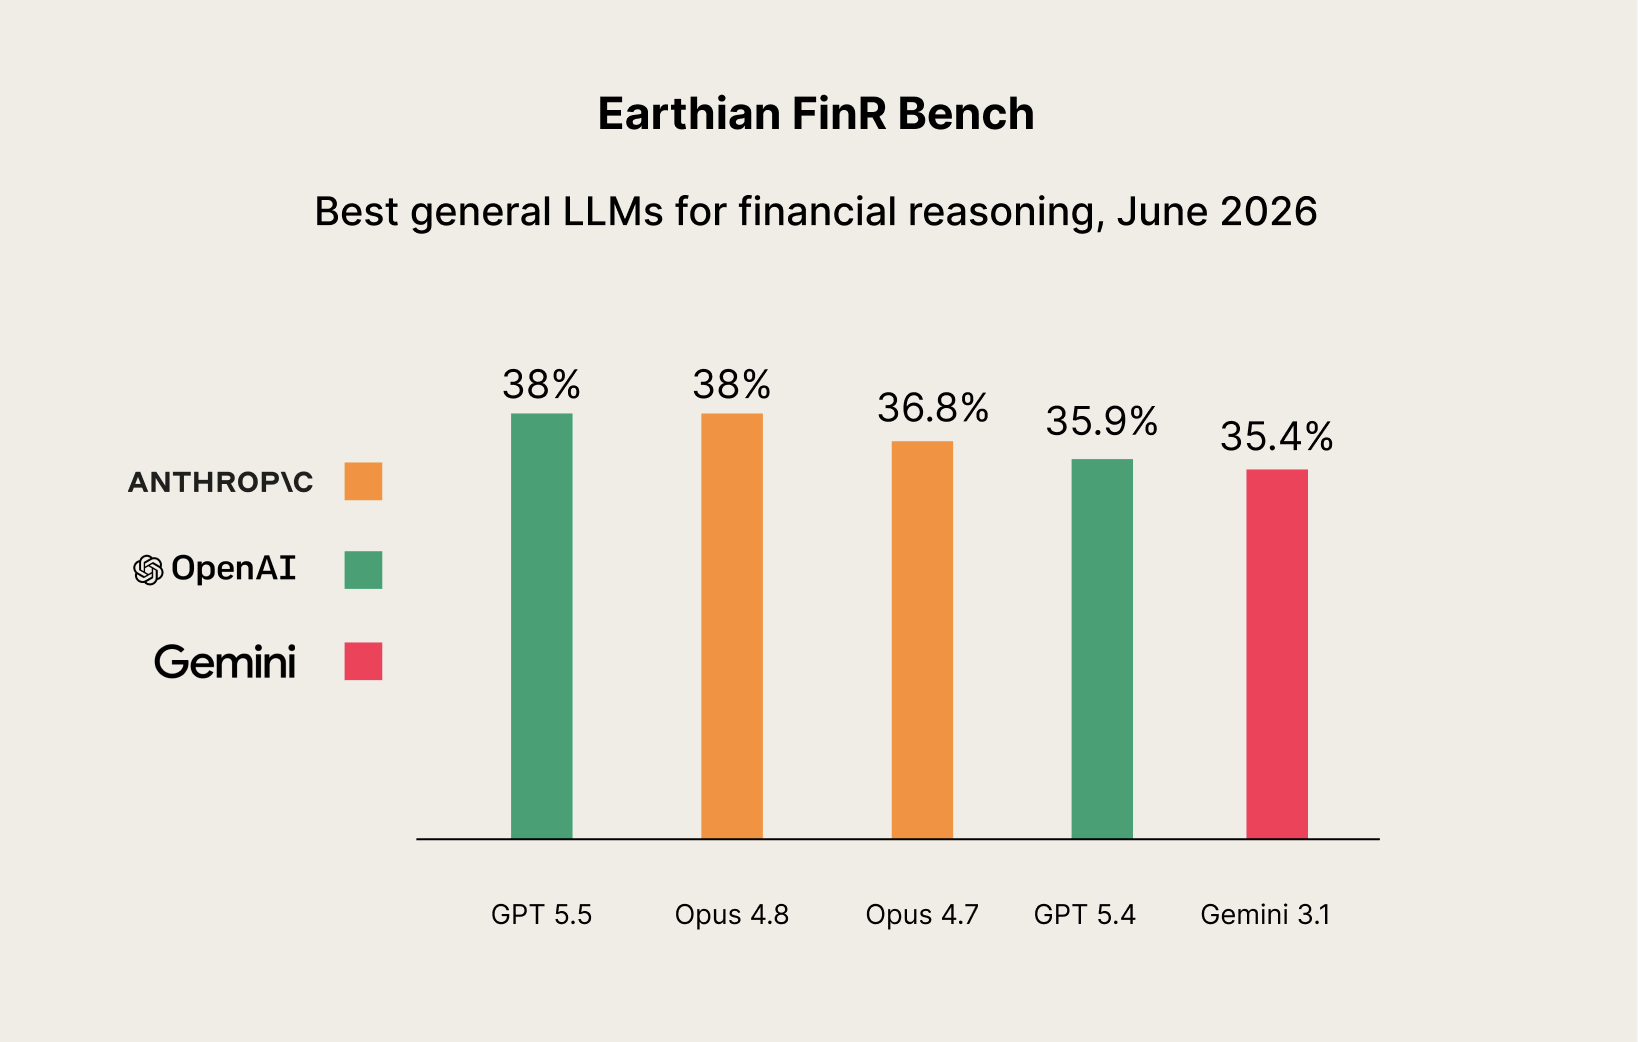
Today, Earthian AI introduces FinR Bench—our financial reasoning benchmark for general-purpose LLMs. Built with input from some of the world's largest financial firms, FinR Bench tests proprietary and open-source models across private equity, credit, insurance, markets, reporting, venture capital, quant strategy, and competitive intelligence—with scores for quantitative accuracy, mathematical reasoning, agentic research, and hallucination resistance.
Today we announce FinR Bench: Earthian AI's financial reasoning benchmark for general-purpose LLMs.
Working with some of the world's largest financial firms, we kept seeing the same gap: there is little standardization or benchmarking on how general-purpose models actually perform in financial reasoning and workflows. Marketing benchmarks rarely reflect the tasks that banks, insurers, asset managers, and private markets teams run every day—and even fewer separate quantitative accuracy from hallucination risk in high-stakes settings.
Why we built FinR Bench
That's why we built FinR Bench—to test both proprietary and open-source models on realistic financial work, with comparable scoring and transparent task design. The goal is not a generic IQ test for LLMs. It is a practical read on which models can be trusted for which financial jobs.
Financial tasks in this release
FinR Bench covers a wide range of financial workflows, including:
- Private equity & M&A due diligence
- Credit and insurance underwriting
- Equity and market research
- Financial close and reporting
- Venture capital sourcing and diligence
- Quantitative trading and strategy
- Competitive intelligence
Each task family reflects how practitioners actually use models: pulling together disparate sources, reasoning over numbers, drafting memos, and stress-testing conclusions before they reach a committee, regulator, or trading desk.
What we measure
The main factors we measure in this version of the benchmark are:
- Quantitative accuracy — getting the numbers, units, and comparisons right
- Mathematical reasoning — multi-step logic across financial statements, ratios, and scenarios
- Agentic research — planning, retrieval, and synthesis across realistic financial workflows
- Hallucination resistance — avoiding fabricated filings, metrics, entities, or citations under pressure
Together, these dimensions capture the difference between a model that sounds fluent and one that can support decisions with money on the line.
Earthian's role
Earthian develops dedicated models for financial reasoning and develops and hosts high-quality financial data for AI models. We believe a standard benchmark can help the public choose the fittest models from major AI labs based on their capabilities in each financial task—not just on broad chat or coding scores.
FinR Bench is part of that mission: open, task-grounded evaluation that complements Earthian's specialized small language models and inference stack for risk and finance.
Working with AI labs
We are in contact with major AI labs to gain deeper technical information on each of these models, and will work to bring the best out of them for the financial sector. As the benchmark evolves, we will publish updates on methodology, task coverage, and model performance.
Acknowledgements
Special thanks to Amaury de Longvilliers of OpenAI and the NVIDIA startup team for their inputs.
What's next
FinR Bench is a living benchmark. We will expand task coverage, refine scoring, and incorporate feedback from financial institutions and model providers. If you are an AI lab, bank, insurer, or asset manager interested in participating, contact us at [email protected].